Edge runtime
A TypeScript application deployed on Cloudflare Workers, with request handling, scheduled work and platform integrations running in an edge environment.
AI systems · Product execution · Agentic development
A multilingual AI companion built as a live, tool-using system—not a single prompt wrapped around one model.
Bizli combines conversational model orchestration, persistent memory, external tools, vision, platform interfaces and a separate diagnostic layer. The project is designed around continuity and resilience: when providers, models or tools change, the system has mechanisms to detect, route around and report failures.
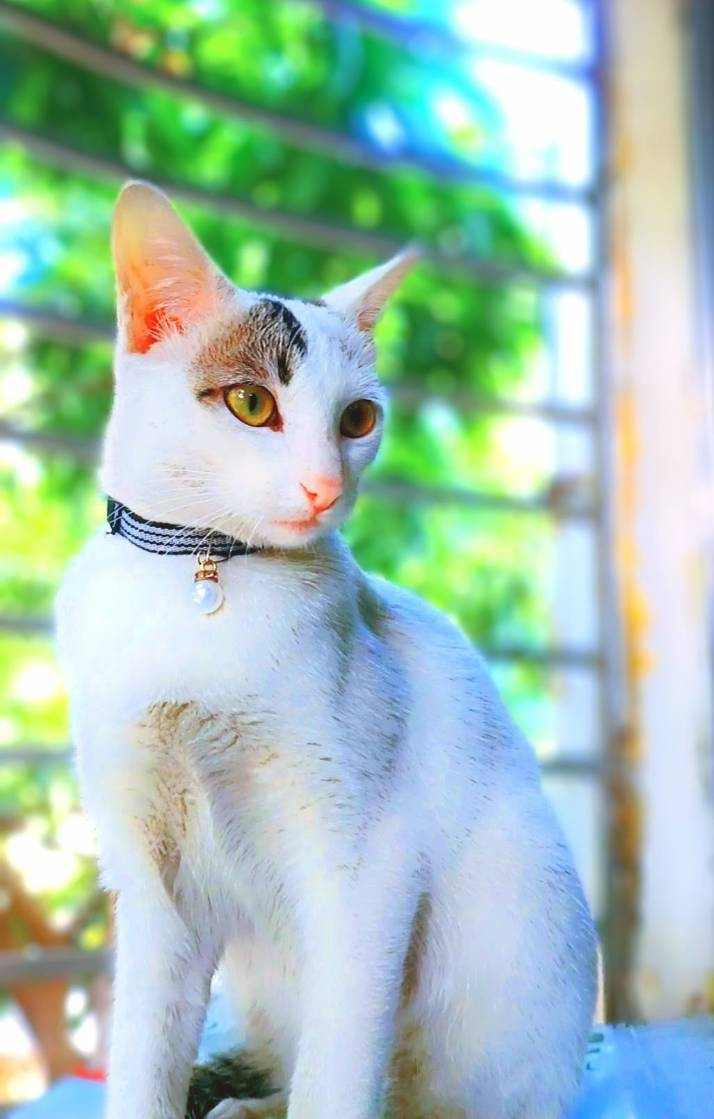
Why Bizli AI exists. It is named after my late cat. What began as a personal memorial became a sustained AI systems engineering project: building a digital companion that can converse, remember, use tools, and remain available to me, my loved ones, and others.
The interesting part is not any single API. It is the coordination between the model layer, memory, tools, interfaces, fallback paths and operational controls.
A TypeScript application deployed on Cloudflare Workers, with request handling, scheduled work and platform integrations running in an edge environment.
Groq is the primary conversational provider. If that route is unavailable or constrained, the runtime can fall back to Cerebras, OpenRouter and Cloudflare Workers AI. These fallback paths provide reduced, text-only functionality rather than full tool parity.
A separate Gemini-powered Lab handles diagnostics and quality analysis rather than sharing the main conversational brain.
Cloudflare KV holds bounded short-term session history and operational state. Supabase PostgreSQL stores selectively extracted longer-term memories, retrieved through embeddings and semantic matching, with importance-ranked retrieval as a fallback.
A model-directed interface exposes 14 registered function tools in the current source. The model chooses when a tool is appropriate; dedicated TypeScript handlers perform the actual operation.
An operational dashboard exposes provider and model health, quotas, errors and test results. Scheduled jobs refresh provider/model discovery, run behavioural probes and generate diagnostic improvement proposals for human approval.
Telegram is the entry point. The Cloudflare runtime coordinates conversation, model routing, memory and tool execution, while a separate diagnostic system evaluates operational quality.
Monitoring · behavioural tests · diagnostic analysis · improvement proposals
Provider order represents the documented fallback design. Available models and provider conditions can change dynamically. The Lab is a separate diagnostic system, not a conversational fallback.
A recorded walkthrough of the diagnostic environment, showing the Lab interface and its operational role alongside the conversational system.
These are concrete mechanisms visible in the published TypeScript source—not claims of custom-trained foundation models or proprietary AI research.
Scheduled probes query provider model catalogues, test candidates, and record the active models. Unavailable models can be dropped and newly available candidates adopted without editing the model list for every change.
The primary provider path tracks usage at the API-key and model level. Soft thresholds, cooldowns and health state help the router avoid constrained key-and-model combinations and reduce the likelihood of rate-limit failures.
Different failures require different responses. The code distinguishes request-size errors, rate limits, provider failures and model-health problems instead of treating every failure as the same retry condition.
Short-term conversation history is bounded and session-aware. Longer-term memories are embedded and retrieved by relevance, with importance-ranked retrieval when embeddings or semantic search are unavailable.
The current source defines a 12-probe suite covering language matching, identity, tool use, privacy, hallucination resistance and conversational behaviour. Six probes run every six hours, rotating through the suite so the full battery cycles every twelve hours; a separate model evaluates the responses.
A daily diagnostic report analyses recent errors and test outcomes, then proposes small behavioural-rule improvements. The proposals are sent for explicit approval; the live assistant is not silently changed by the diagnostic model.
The conversational layer can answer directly or decide to invoke a registered tool. Tool execution is handled by explicit TypeScript functions connected to external services.
I define product requirements, set priorities, direct implementation through coding agents, assess proposed changes, investigate failures, make architectural and integration decisions, and evaluate the deployed system.
I did not begin with a formal software-engineering background. I began with a vision and learned through building. When I encountered technical limits or an approach failed, I investigated alternatives, experimented, evaluated the results and adapted. Over time, this became a more systematic way of learning and executing.
My working cycle: Envision → Investigate → Experiment → Evaluate → Adapt → Implement → Repeat.
The repository is public, allowing the technical work to be inspected. The Telegram bot provides a direct way to interact with Bizli.
Technical summary prepared from the public repository's README and selected TypeScript modules, reviewed on 7 November 2026. Provider availability and deployed configuration can change. This page does not claim independent security certification, formal load testing or a third-party code audit.